Comparing UIA and CDP: How Instrumentation Errors Masked Automation Click Performance
A measured Skynet field study of UIA, CDP, coordinate mapping, occlusion, and provider acceptance with corrected experiments and raw evidence.
Read storyPublished articles
62
Live across automation, AI, and engineering tracks.
Active topics
17
Topics with at least one published article.
Publishing cadence
14
14 articles shipped over the last 30 days.
Last update
Fresh coverage streamed in recently.
Explore high-intent archives built for discoverability across AI models, market analysis, and macro-economic coverage.
Fresh playbooks, tooling notes, and activation guides curated by the automation desk.
Open archive 21 articlesFoundation-model launches, agent workflows, benchmark analysis, and implementation playbooks for applied AI teams.
Open archive 17 articlesFresh playbooks, tooling notes, and activation guides curated by the automation desk.
Open archive 14 articlesGlobal publishes source-verified country editions for the United States, China, Spain, France, Germany, Brazil, Japan, India, Indonesia and Saudi Arabia - each on its own URL, in its local language variant, and cross-linked to the other editions.
Open archive 11 articlesLatest tech innovations and trends
Open archive 10 articlesExplores solutions for large-scale organizations, focusing on tools and platforms that optimize operations, customer engagement, and business processes.
Open archive 10 articlesFresh playbooks, tooling notes, and activation guides curated by the automation desk.
Open archive 5 articlesBusiness updates, company milestones, and investor content.
Open archive
A measured Skynet field study of UIA, CDP, coordinate mapping, occlusion, and provider acceptance with corrected experiments and raw evidence.
Read story
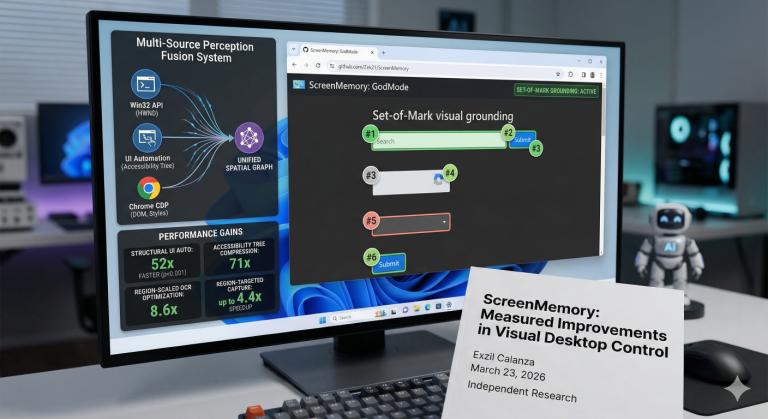
Abstract Autonomous desktop agents remain far below human performance on real-world operating-system benchmarks, with the best reported results reaching only 12.24% task completion on OSWorld compared to a 72.36% human baseline. We hypothesize that the primary bottleneck is not large-language-model reasoning but rather the
Read story