platform
Stop Treating AI Agents Like Junior Employees
AI agents need distributed-systems discipline: durable state, idempotent retries, tracing, scoped permissions, and explicit human approval.
Read story AI agents need distributed-systems discipline: durable state, idempotent retries, tracing, scoped permissions, and explicit human approval.
Read story
Four open-source Skynet products reveal why verification must follow the product layer—and why unavailable evidence is not a pass.
Read story
Two Windows hosts on one Chrome build returned different accessibility-tree node totals. The experiment shows why viewport and node roles must be reported.
Read story
A controlled Chromium and Firefox study separating UI settlement, correlated transport completion, and action-specific semantic success evidence.
Read story
A measured Skynet field study of UIA, CDP, coordinate mapping, occlusion, and provider acceptance with corrected experiments and raw evidence.
Read story
I built RStackBench to test when browser agents look successful but fail the requested state: 288 conditions, 864 traces, and an open preprint.
Read story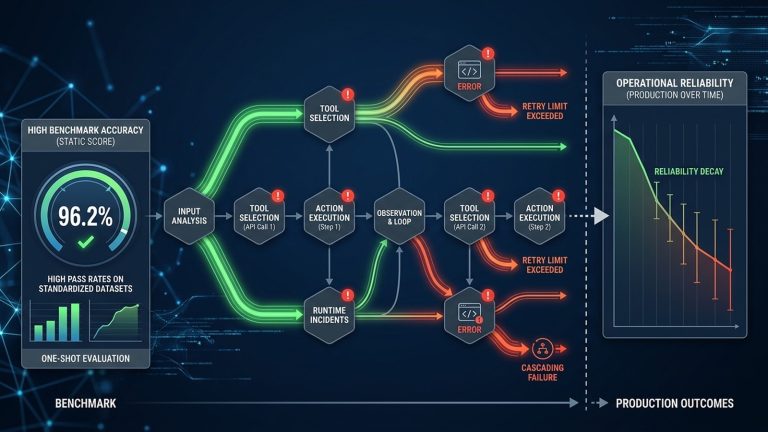
Benchmark accuracy and operational reliability are different properties. Two 2026 papers show capability gains barely moved reliability.
Read story
A preregistered 600-case study showing why route verification needs final-URL coherence plus application-specific semantic anchors.
Read story
A frozen-evidence audit of 10 verified-live remote job posts found 8 of 9 hard geographic constraints were absent from search snippets.
Read story
An RX 6600 DirectML benchmark verified both LSTM nodes on DirectML, found CPU median latency lower, and withheld 1,062 unvalidated forecasts.
Read story
I wanted the small, direct feel of a raw Chrome DevTools connection in Firefox without pulling in a full automation framework. Firefox no longer exposes CDP, so I built a roughly 700-line Python adapter that gives my code a CDP-style Tab API over WebDriver
Read story
A proof-backed field note on separating deterministic risk gates from neural review, using a real Gemini 3.5 and ChatGPT research run and official 2026 guidance.
Read story Chat with us